ScreenGawk
Youtubers React To Scraping of Their Videos For AI Without Consent
Youtubers this week were surprised to discover that many of their videos had been scraped for the purposes of training AI models from large companies including Apple and Anthropic.
The dataset, originally intended for use by smaller individuals and companies with less resources, has been cited in multiple legal cases and contains videos from some major content creators including Mr Beast and PewDiePie as well as videos promoting flat-earth theories.
Creators Surprised and Critical
Claudio Schwarz/Unsplash
When creators were informed by Proof News, those who reacted were publicly critical of the unauthorized use of their material.
They were critical of how it had been used without their consent, with no compensation and of how it allows larger companies to absolve themselves of blame by retrieving the data via a third party.
Large Dataset
Barez Omer/Unsplash
The dataset collects video captions using Youtube's own API from 173536 videos from more than 48000 Youtube channels.
It also includes data from Wikipedia, books and other sources.
Against Youtube's Terms of Service?
Sara Kurfess/Unsplash
The scraping of data in this way may be against Youtube's terms of service, although similar cases are still being debated legally.
The terms of service say that automated services such as scrapers can not be used unless they are search engines that follow a specific set of rules or have explicit permission from Youtube.
Uncompensated Work
Rebel Wisdom/Wikimedia
David Pakman, whose Youtube channel has over 2 million subscribers, responded to the revelation by pointing out that no one had asked for permission to use his team's work.
"No one came to me and said, 'We would like to use this' ... This is my livelihood, and I put time, resources, money, and staff time into creating this content," he told Proof News.
Lack of Consent
Joanna Kosinska/Unsplash
The CEO of Complexly, who produce SciShow, Julia Walsh, also expressed disappointment at the lack of consent-seeking.
She said: "We are frustrated to learn that our thoughtfully produced educational content has been used in this way without our consent."
Big Tech Responds
TechCrunch/Wikimedia
Anthropic responded by claiming only that there had been no violation of Youtube's terms of service at their end.
Their spokesperson, Jennifer Martinez, said: "The [dataset] includes a very small subset of Youtube subtitles... Youtube's terms cover direct use of its platform, which is distinct from use of the dataset."
Where Does the Dataset Come From?
Rawpixel/123RF
The data was collected by a company called EleutherAI, which had originally intended for the data to be used by individuals or smaller companies with limited resources.
Despite this intention, larger companies have also used the dataset for their own purposes.
Avoiding Blame
Ramsey Cardy/Wikimedia
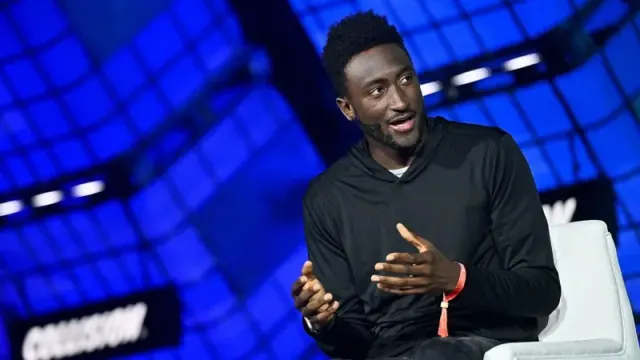
A Youtuber who reviews tech and also had his videos scraped, Marques Brownlee, believes that Apple use the dataset to sidestep culpability.
On X, he posted: "Apple technically avoids 'fault' here because they're not the ones scraping. But this is going to be an evolving problem for a long time"
Ongoing Legal Issues
Tingey Injury Law Firm/Unsplash
The dataset is already a part of some major legal battles, including one concerning OpenAI.
OpenAI has claimed that using data scraped without consent is 'fair use' but none of the court cases have yet concluded.